
Sequential delivery is a relay race
Traditional software delivery is a relay race. Requirements wait on stakeholders. Design waits on requirements. Engineering waits on design. QA waits on code. Release waits on QA. Every handoff adds idle time, context loss, and cost.
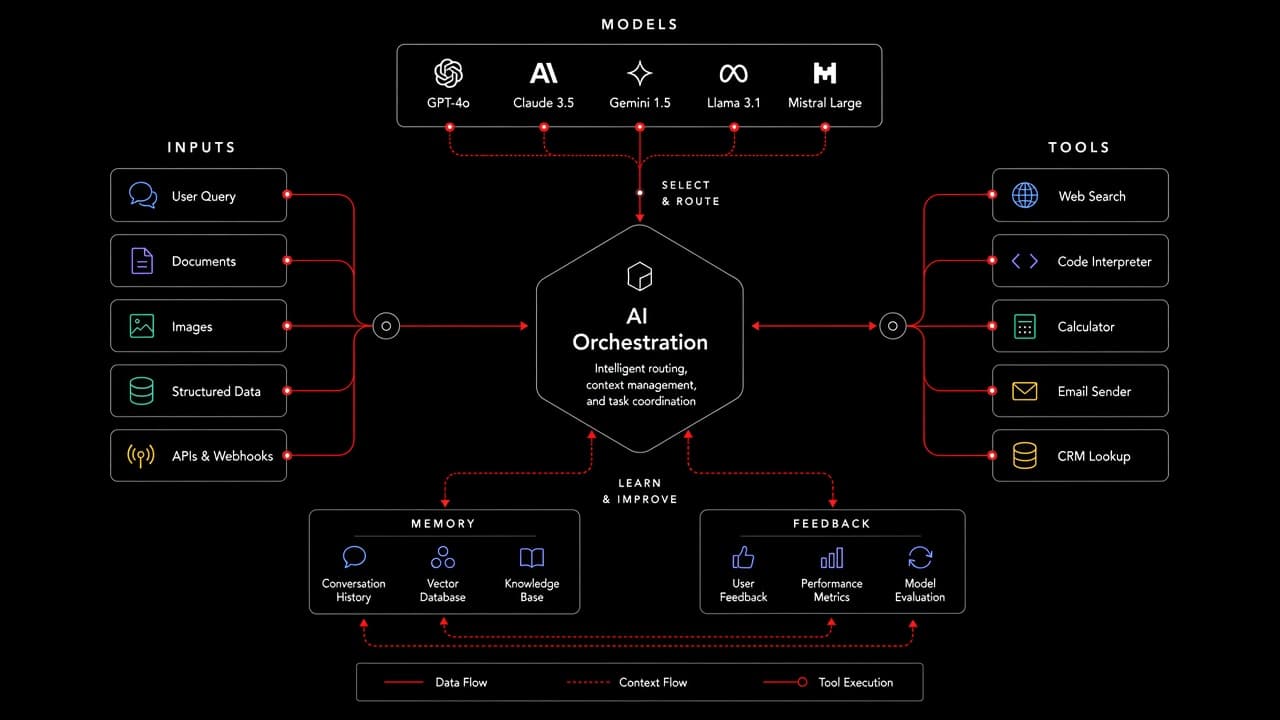
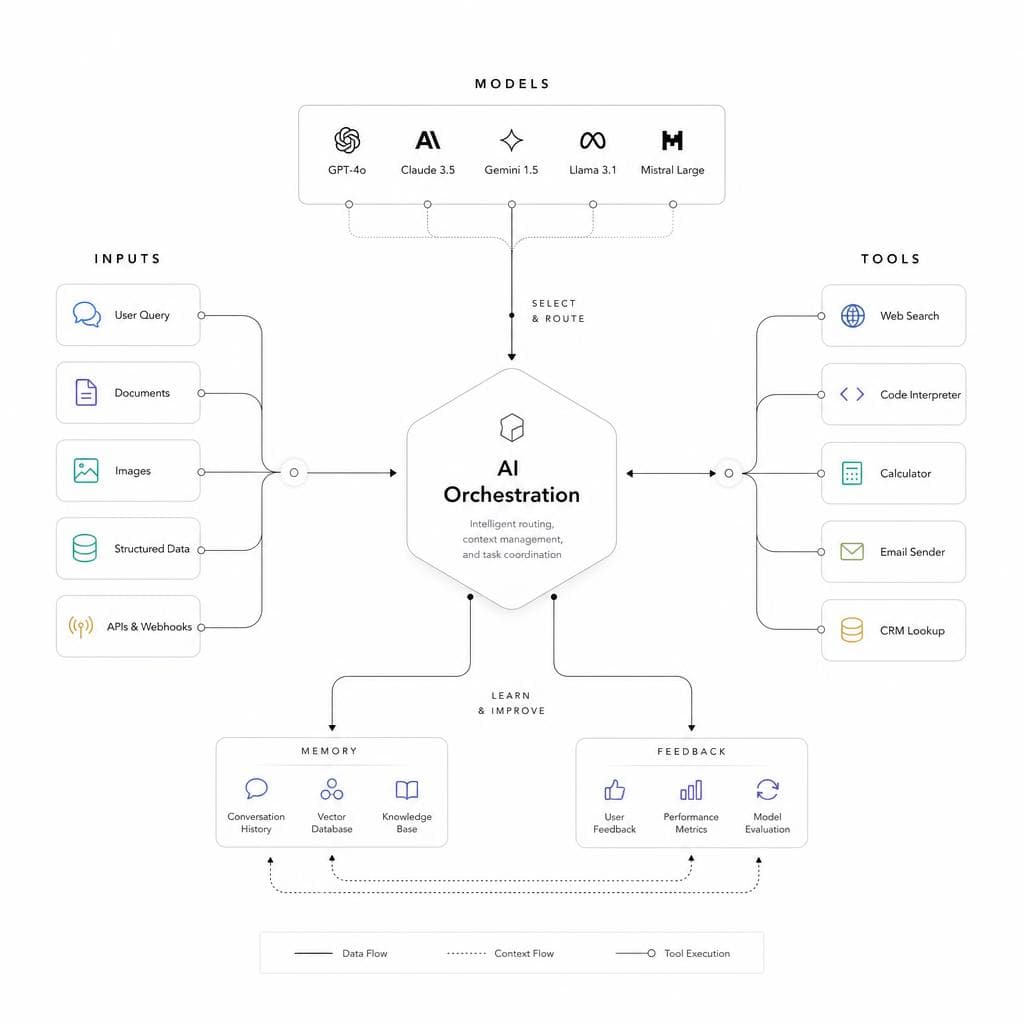
AI-orchestrated SDLC flips that model. Coordinated AI agents run planning, coding, testing and documentation in parallel, supervised by senior engineers in Baner, Pune. Humans set product direction, accept risk, and approve architecture, security and production readiness. Agents draft specs, code, tests and documentation, run QA and integration checks continuously, and propose changes — they do not ship without a human gate.
What parallel tracks look like in practice
Renaissa AI Labs publishes a 4X faster and 4X more affordable delivery model versus sequential software agencies. The comparison is structural: parallel tracks instead of a relay. Calendar time and fully loaded cost benchmarks for a controlled sample are not published on the marketing site; treat the multiplier as a published operating model, not a verified industry study.
The long-form page at /ai-orchestrated-sdlc describes the human–agent split. Requirements and architecture can advance while implementation and automated validation run on another track. Integration debt is meant to surface continuously, not only in a final QA week.
How this connects to client services
From Baner, Pune we deliver full product builds, AI workflow automation, custom ML models, enterprise integrations, and AI strategy consulting — with the same orchestration idea behind internal products such as Lex, Tyren, and RenBooks. Engagements are sprint-based: discovery in one to two weeks, MVPs in four to eight, full products in eight to sixteen. Prices are quoted after discovery; we reply within 24 hours on sales@renaissa.ai.
If you are comparing vendors, ask whether their delivery is still sequential while your roadmap expects parallel feedback. Our consulting and build pages spell out engagement bands without inventing rupee amounts on a blog post.
What to evaluate before you buy
For enterprises evaluating AI in engineering, the question is whether your delivery system still serialises work that could run in parallel with proper gates. Copilots alone do not change calendar time if QA and release still wait on a finished feature branch.
Read the orchestrator-focused companion at /blog/4x-faster-development-how-we-do-it, then /services or /consulting if you want a written quote after a short discovery call.
Client visibility
Ask for sprint demo cadence in your statement of work. Parallel delivery only helps when stakeholders review increments weekly, not only at UAT.